A request finds a reusable prefix, so the scheduler treats it as ready. In a hybrid language model, the recurrent state it needs may still be under construction elsewhere in the same round.
RadixFlow's October 13 paper identifies resulting head-of-line blocking. Its traversal skips the locally blocked consumer and fills available slots with independent work, reducing latency in the evaluated hybrid-model workloads. Read the research paper.
A cache hit can still leave a worker idle
Prefix reuse is one of the basic efficiencies of language-model serving. Requests sharing an initial stretch of text can reuse cached computation instead of processing it again. A scheduler then tries to assemble a batch of requests ready to execute. In a conventional full-attention system, a matched prefix is usually a good indication that the associated work is available. Hybrid models complicate that assumption because recurrent state can introduce dependencies between branches being processed in the same worker round.
RadixFlow studies the idle capacity created by that mismatch. The relevant resource is not only how much computation has been reused, but whether the scheduler can consume the required state now. A high cache-reuse rate can coexist with unnecessary waiting.
A blocked branch should not block the queue
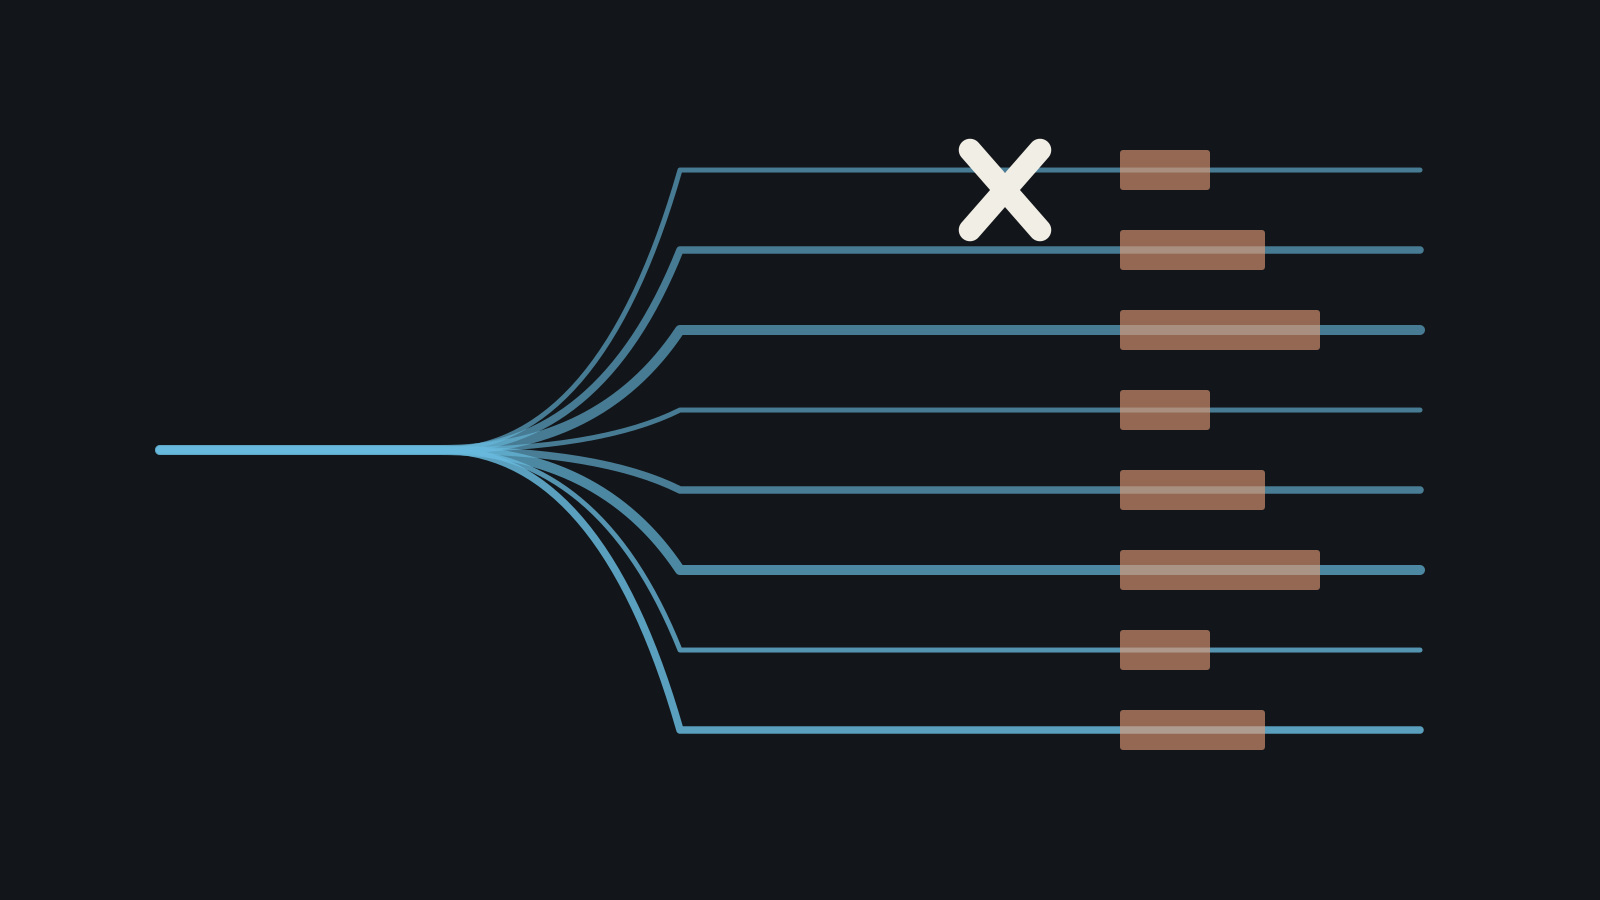
The paper distinguishes a producer branch, still computing recurrent state, from a consumer branch that needs that state. In the native scheduler studied, encountering the blocked consumer stops the scan of the waiting queue. Independent requests behind it can therefore miss available batch slots even though nothing about their own dependencies prevents execution. The authors call the resulting gaps execution bubbles.
RadixFlow separates prefix matching from state readiness. Its traversal leaves the blocked consumer waiting until a later round while continuing to look for feasible independent work. It retains the native state check rather than pretending the unavailable state is ready. The change concerns which other work can proceed around a dependency, making a global barrier into a local wait.
Reuse barely changes while execution improves
Across five hybrid models, the authors report mean-latency reductions of three to twenty-four percent and reductions in worker rounds of eleven to forty-four percent, with almost unchanged reuse. The result is instructive because a reuse metric alone would largely miss the improvement. The same cached work becomes more valuable when the scheduler assembles executable batches around it more effectively.
Ablations on larger Qwen3.5 models attribute most of the gain to traversal. A full-attention control shows little benefit, supporting the argument that the intervention addresses an architectural dependency rather than a universal scheduling defect. This also limits the inference: the reported saving should not be transferred unchanged to a serving stack whose state model does not create that blockage.
The measured workload is narrower than a production service
The paper’s limitations describe candidate-conditioned prefill followed by one generated token, with model, budget and arrival settings frozen. Worker-call timing and decoded-output agreement are the reported measures. Broader load sweeps, production scheduling and finer dependency tracing remain extensions. This qualification is especially important because queueing effects can change with traffic.
The intervention also preserves exact-prefix namespaces and does not introduce approximate semantic reuse. Its gains should therefore be attributed to scheduling feasible work around a state dependency, not to making looser guesses about which contexts match. Keeping that contract visible helps separate a latency optimisation from changes that might alter what state the model is allowed to reuse.
Fewer rounds are not a proportional speedup
The remaining rounds can become heavier after previously idle slots are filled. That is why the reduction in worker rounds need not match the latency reduction. End-to-end measurement remains necessary, ideally under realistic request arrivals and prompt-sharing patterns. A workload with few blocked consumers may offer little opportunity; a busy mixed workload may behave differently from a fixed batch.
A serving assumption can be correct for one architecture and inefficient for its successor without producing an obvious correctness failure. RadixFlow shows why infrastructure reviews need to revisit the meaning of readiness as well as the mechanics of reuse. Better weights are not required to recover time that the scheduler has already left unused.
Questions, news tips or corrections? Contact [email protected].