An expert trajectory is a rich teaching object: it includes observations, actions and the order in which a task unfolded. Feeding the whole trajectory into every decision is also expensive. A summary saves tokens, but it may leave the agent to reconstruct how general advice translates into the action choices available right now.
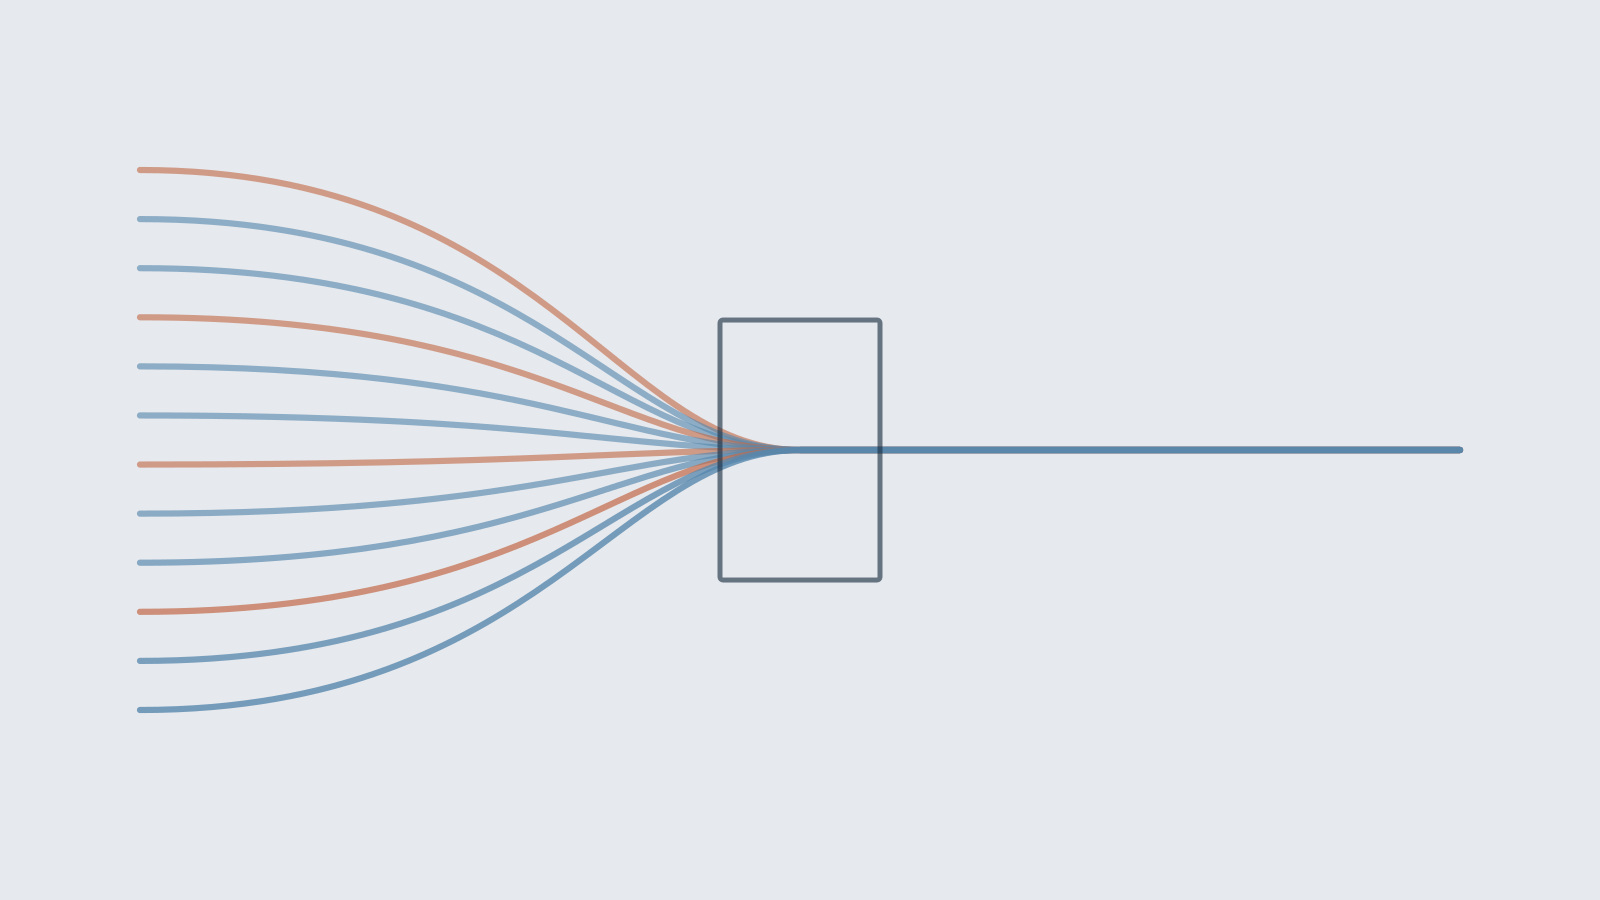
CB-Agent asks whether demonstrations can supervise that choice directly. Its compact learned object is a rule for scoring candidate actions using frozen language-model features. The system remembers part of the expert’s decision structure rather than continually rereading the expert’s story. That changes both the efficiency and the failure modes of demonstration reuse.
The training unit is an environment-action decision
CB-Agent, posted October 10, fits a concept vector from expert environment-action decisions and combines it with frozen model features to score candidate actions. The demonstrations are absent from the action-scoring context at runtime. The authors evaluate the method in TextWorld, ALFWorld and ScienceWorld. Read the research paper.
The method extracts decision points from expert trajectories and fits a concept vector by maximum likelihood over candidate actions. At runtime, the concept combines with frozen model features and priors to define an action distribution. The action-scoring context does not need to contain the original demonstrations.
This is adaptation even though the language-model backbone stays frozen. Calling the deployed scoring step demonstration-free is accurate; implying that the system learned without expert examples would not be. The supervision has been compiled into a compact parameter rather than removed from the process.
Candidate actions define the learned decision space
A scoring rule operates over the alternatives supplied to it. In a structured interactive environment, those candidates can make the expert’s choice a well-defined supervised target. In a changing tool environment, candidate generation and descriptions become additional sources of error. A rule cannot favour an action that was never included in the set.
This boundary is important when transferring the approach. Better action ranking and better discovery of available actions are different capabilities. The paper’s frozen-feature method addresses the former in its evaluated environments. An unrestricted agent may also need to construct arguments, identify missing preconditions or discover a new tool. Those tasks should not be counted as solved because the compact concept works well once candidates are given. The useful generalisation is therefore conditional: demonstrated decision structure can be compressed when the interface preserves the choices and context that make that structure meaningful.
A rule can complement reflection
The paper evaluates TextWorld, ALFWorld and ScienceWorld at three model sizes. It reports the highest cross-benchmark average among compared methods at each size, with additional ALFWorld experiments supporting a contribution beyond prior-only scoring. Combining the learned concept with Reflexion produces further gains in that setting.
Those environments make candidate actions and consequences more structured than unrestricted software or physical tool use. The results support reusable action scoring within the evaluated interfaces. They do not establish that a concept trained on one environment automatically handles new tool semantics, permissions or hidden preconditions.
Compression removes the episode’s qualifications too
A full demonstration may reveal why an action was appropriate: a door was unlocked, a container was empty or a prerequisite was already satisfied. A compact score rule can lose some of that explanatory detail. Its reliability depends on whether the features and current context preserve the conditions that matter.
The wider opportunity is to store procedural experience in a form that directly influences choices without occupying the prompt. The corresponding operational task is to version and invalidate those rules as environments change. Efficient memory is not only a smaller representation; it is one whose conditions remain visible enough to know when it should stop being used.
References
Questions, news tips or corrections? Contact [email protected].