Speculative decoding tries to approve several guessed tokens at once. In an offloaded mixture-of-experts model, those guesses can summon different expert weights from host memory, turning a larger draft into more waiting.
SpecFit, posted October 11, chooses draft subtrees by predicted throughput rather than acceptance length. Its cost model includes the union of experts activated across the candidates. The authors report gains on their evaluated summarisation and mathematics workloads. Read the research paper.
More speculation can make an offloaded model slower
Speculative decoding appears to offer a simple bargain: a small drafter proposes several tokens, and a large target model verifies them together. If enough guesses are accepted, the target completes more output per expensive pass. A mixture-of-experts model introduces another cost. Different candidate tokens can activate different experts, and offloaded expert weights must travel from host memory to the accelerator. A larger draft can therefore create more transfer work than its additional accepted tokens justify.
SpecFit puts that transfer cost into the selection objective. It asks which part of a draft tree will produce the most expected progress per unit of real cycle time, rather than optimising acceptance length as though every candidate were equally expensive.
Experts make the cost depend on the whole subtree
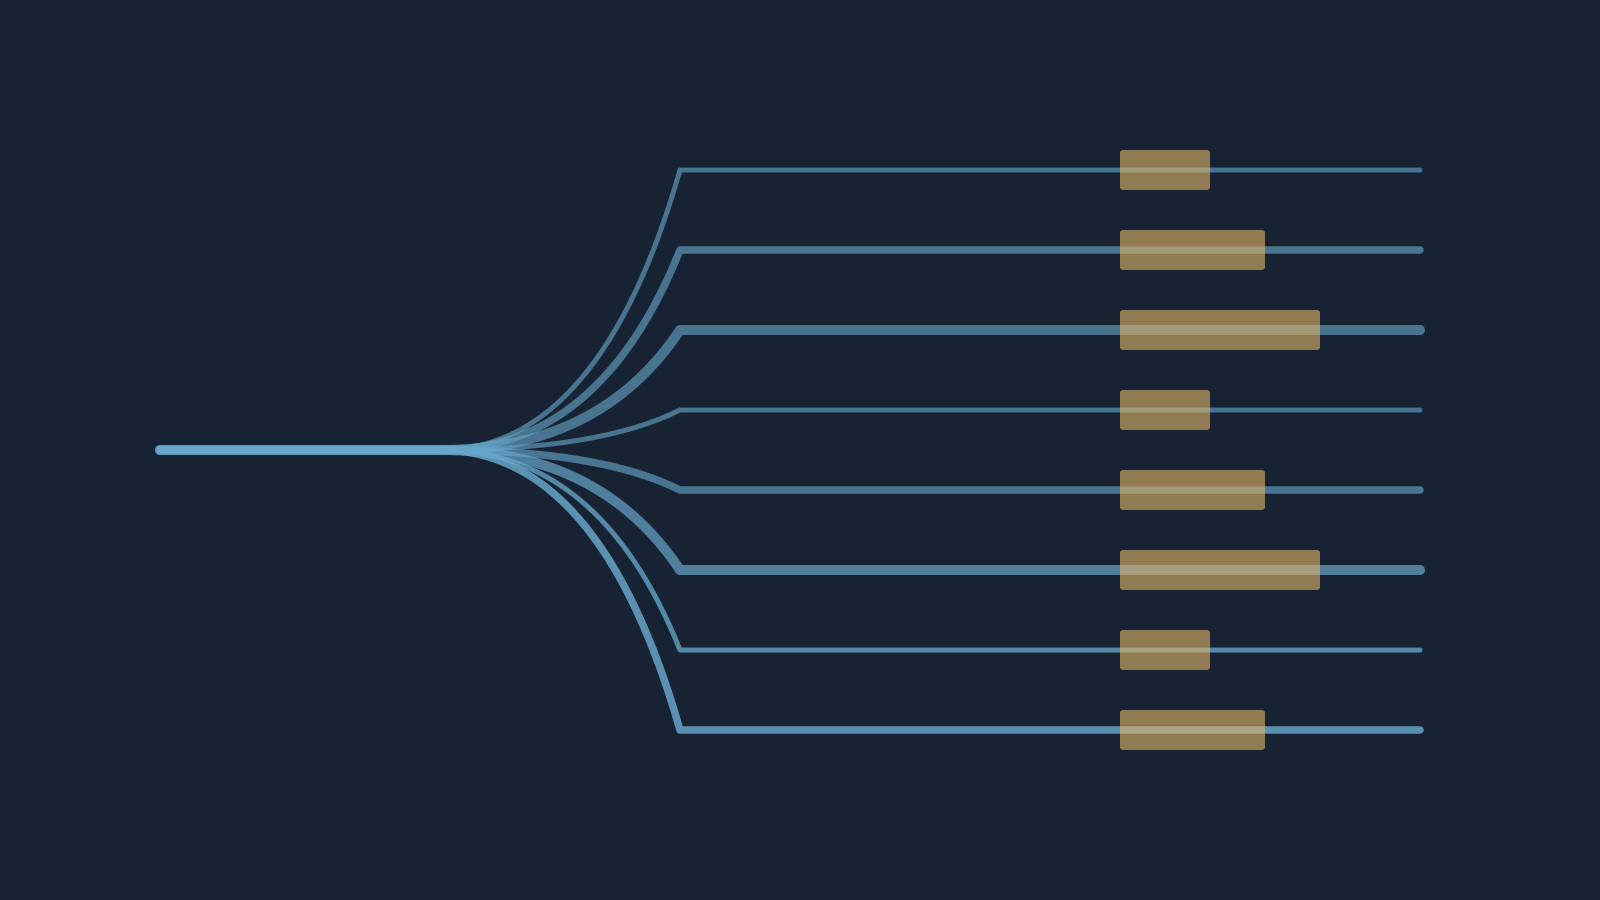
The system estimates committed tokens from draft-path probabilities. It predicts cycle time using node count and the union of experts activated at each layer. That union matters: two candidates using the same expert can share a transfer cost, while another candidate may require weights not otherwise needed. The marginal cost of a node depends on the nodes already selected.
The authors formulate expert coverage as a monotone submodular function and search exactly over ancestor-closed subtrees. Keeping ancestors is necessary because a draft path must remain executable. Running the search after each draft level also provides a stopping decision: further drafting is worthwhile only if its predicted throughput improves. The target model then verifies the selected result without modification.
The comparison separates two cache conditions
On CNN/DailyMail summarisation and a GSM8K subset with Qwen3-30B-A3B, SpecFit is reported to decode 21.6 and 7.0 percent faster than EAGLE-3 with the same expert cache. Against vanilla EAGLE-3, the corresponding speedups are 1.97 and 1.72 times. The same-cache comparison helps isolate the value of choosing the speculative work, rather than attributing every gain to a more favourable storage setup.
These are results for offloaded inference under the paper's conditions. If experts are already resident on a different accelerator, transfer may cease to dominate, and the preferred tree can change. A cost-aware objective is useful precisely because a single draft shape is not necessarily optimal across memory systems.
The search does not alter the target model
SpecFit keeps the EAGLE-3 drafter and candidate generator fixed. It changes drafting depth and the subset sent to verification, without retraining a component or changing the router. All experts routed for selected target tokens still execute. This distinguishes it from approaches that reduce loading by changing which experts the target is allowed to use.
The exactness of the subtree search is also bounded: it finds the best predicted ratio within its feasible family and cost model. It does not prove that the prediction equals the fastest possible execution on every machine. That separation is useful when reproducing the result. First verify the controller’s choice under the stated model, then check whether the predicted saving survives actual expert-cache and transfer behaviour.
The best predictor is not always the best accelerator
The decision requires a sufficiently accurate cycle-time model. Incorrect estimates of transfers, cache hits or computation can choose a subtree that looks economical but runs poorly. A deployment should therefore report predicted versus measured time, bytes transferred and committed tokens, including cases where the controller stops earlier than an acceptance-focused policy.
Speculative decoding depends on the memory system as well as the drafter’s predictions. Improving a drafter's token accuracy does not settle how much of its output is worth verifying. On offloaded expert models, the useful question is what new hardware work each additional guess causes, and whether the expected accepted output repays that work. SpecFit makes that dependency explicit instead of assuming that a longer accepted draft must mean a faster service.
Questions, news tips or corrections? Contact [email protected].