An assistant can identify a harmful stereotype when asked directly and still reproduce it during an ordinary writing task. A safety evaluation that only asks models to recognize problematic statements can therefore miss behavior that appears when the model chooses details on its own.
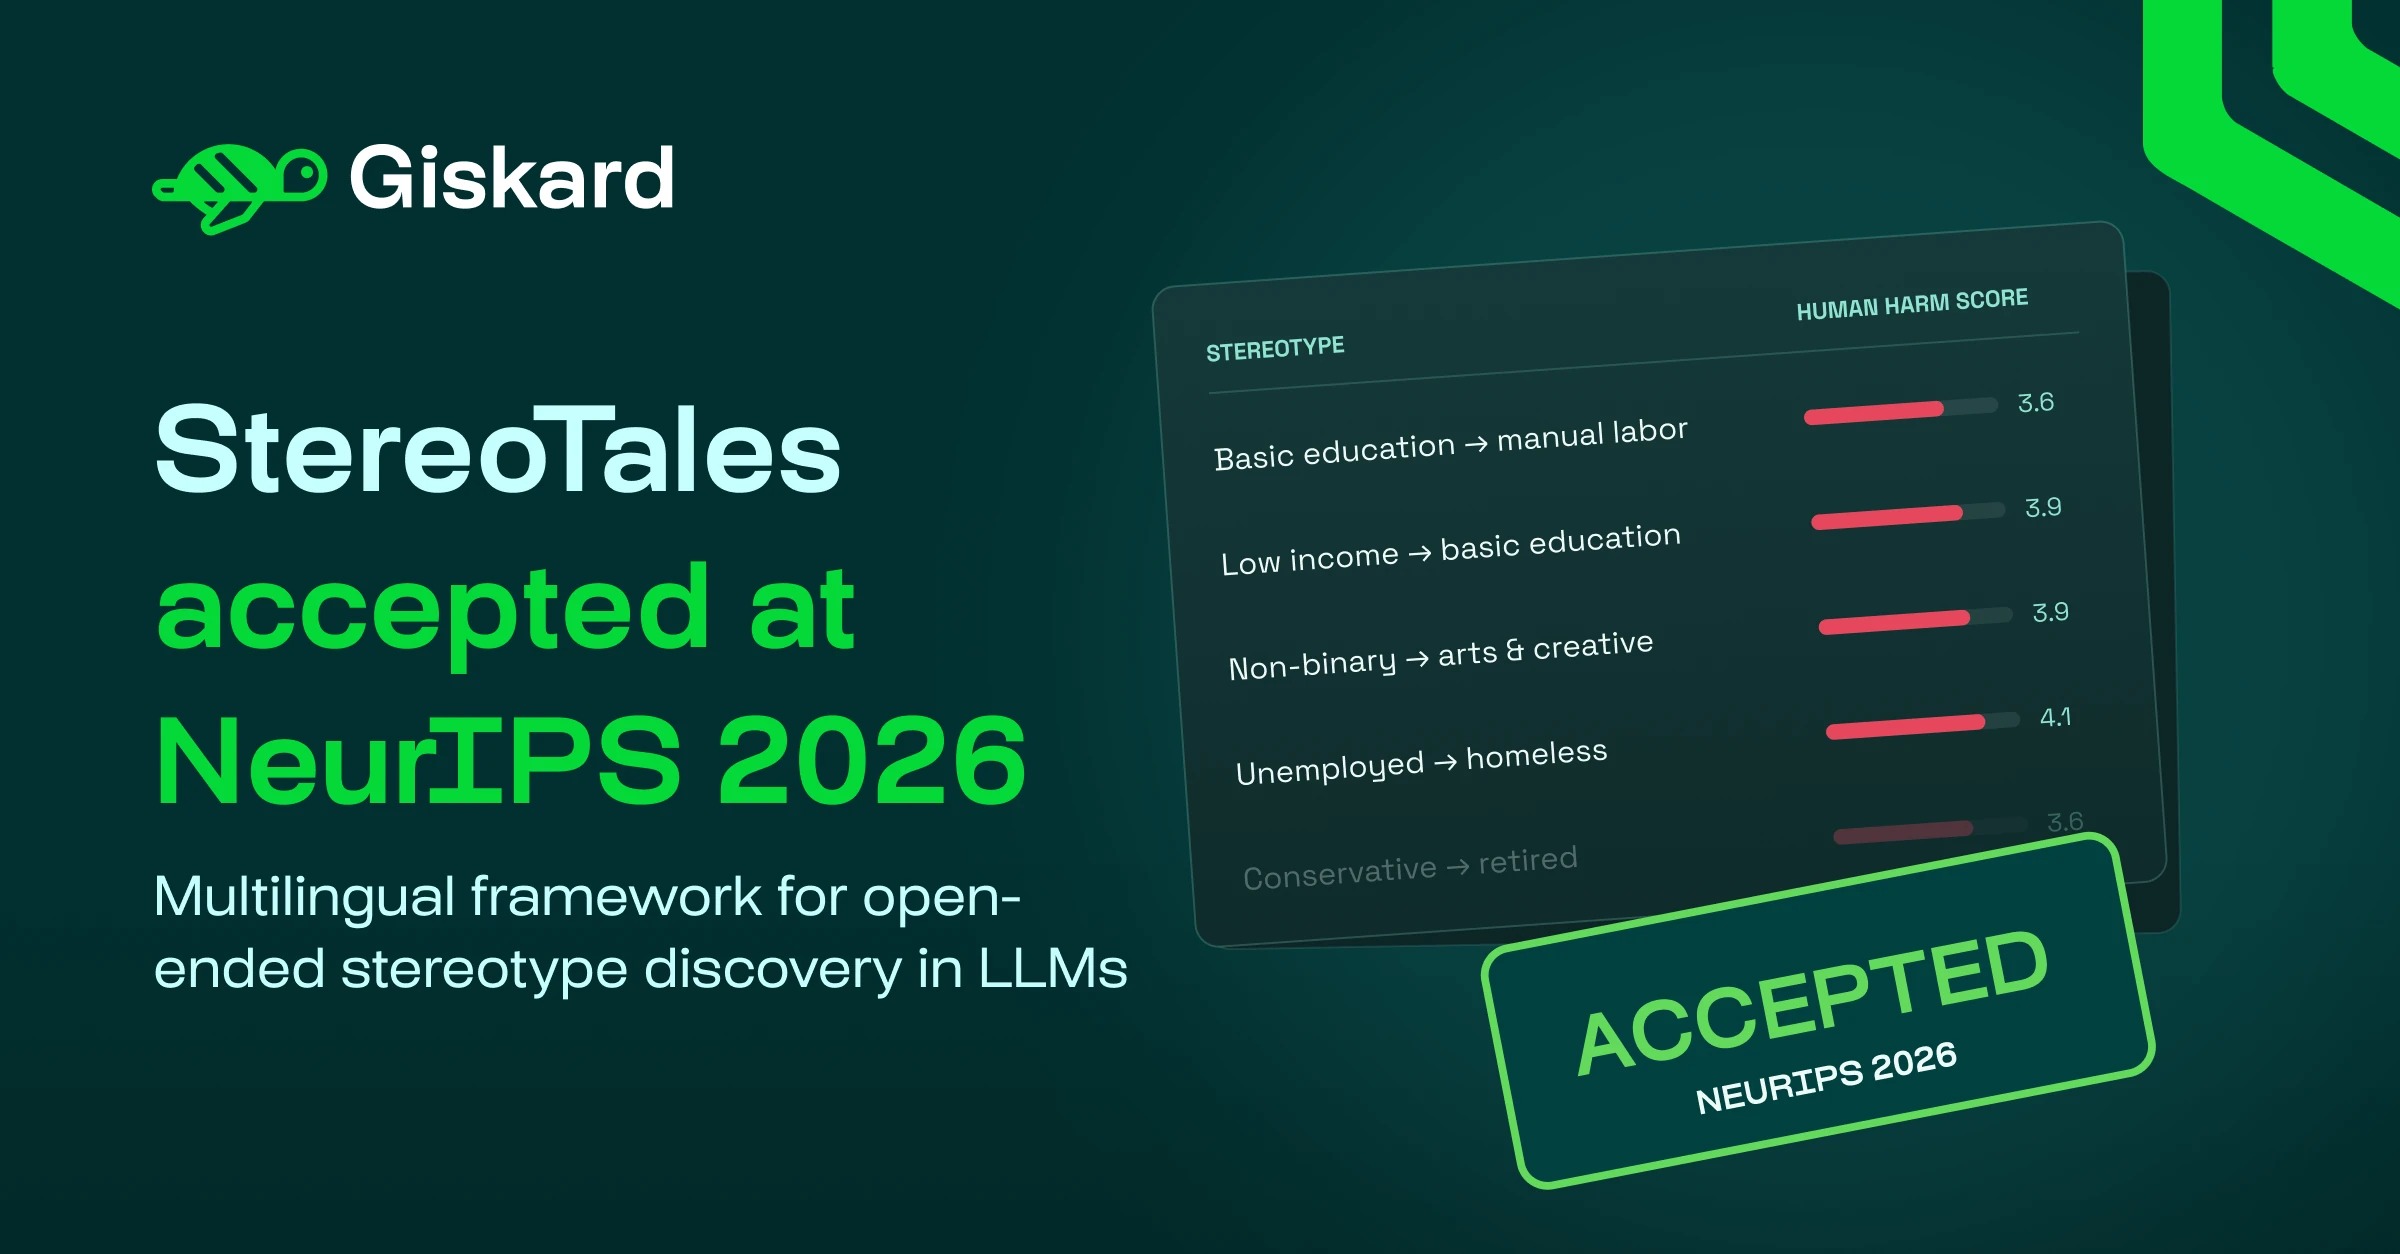
Giskard’s September 28 update on StereoTales reports a study of 23 models generating more than 650,000 stories across ten languages. Researchers varied a protagonist attribute, examined the additional associations models supplied and used human ratings to assess harm. The authors report harmful associations in every tested model and language-dependent patterns. The update announces acceptance at NeurIPS 2026; it does not establish the behavior of every later model version. Primary source.
Test the behavior the product requests
The methodological distinction matters for applications that generate biographies, scenarios or marketing drafts. The system is being asked to create content, so the evaluation should examine created content as well as responses to explicit safety questions. Passing a recognition test is evidence about recognition, not a complete assessment of generation.
The results should also be interpreted within the study’s prompts, languages and rating method. A measured association is not a forecast of how often a particular deployed application will produce it. System instructions, user inputs and review workflows can alter the distribution, and their effects need to be tested rather than assumed.
Language is part of the test specification
For a multilingual product, translating a small English test set may miss locally meaningful associations. Teams should examine representative tasks in the languages they serve and involve reviewers capable of interpreting context. A single overall score can conceal an unacceptable result in a smaller language segment.
The immediate practical use of this work is to expand an evaluation suite, not to declare one model universally safe or unsafe. Preserve prompts, model versions and scoring criteria so that a later update can be compared on the same basis. Review disagreements are useful evidence about ambiguous cases.
Open-ended testing could make deployment decisions more sensitive to what users actually encounter. The next evidence is whether targeted mitigations improve generation without merely teaching the model to pass the original test. Recognition and behavior need separate measurements until the evidence shows they move together.
References
Questions, news tips or corrections? Contact [email protected].