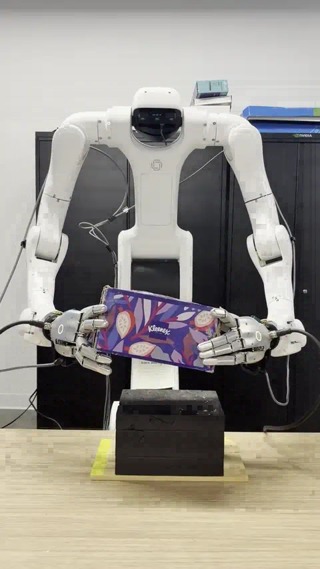
A human video contains the appearance of a useful skill, but usually lacks the robot commands needed to teach it. NVIDIA’s Video to Data toolkit fills that gap through reconstruction, simulation and an intermediate robot expert. Its most revealing example is a tissue-box task where simulation pretraining followed by a little real adaptation succeeded, while the reported real-only alternatives did not.
V2D is a toolkit and a challenge, not one model
NVIDIA opened its Video-to-Data challenge on September 21, 2026. The associated released toolkit converts human demonstrations into simulation assets and robot-training data. Its documented end-to-end example now reaches GR00T N1.7 fine-tuning and closed-loop evaluation, rather than stopping at reconstructed footage.
These are separate contributions. The toolkit supplies an executable route from video to action-labelled experience. The competition measures where routes like it break. Neither means that a single new model watches arbitrary internet footage and immediately operates any robot.
First find the action, then rebuild its scene
The ingestion workflow segments recordings into action clips, builds an entity-relation graph and stores frame embeddings. A downstream query can retrieve the relevant interaction instead of reconstructing every frame. The shipped configuration uses Qwen3-VL-8B-Instruct and Google SigLIP2; Cosmos3-Nano is an optional vision-language model choice, not a required video generator.
Selected clips pass through reconstruction modules that estimate depth, object masks, textured meshes, object poses and human motion. Those outputs describe a scene and a demonstration; they are not yet a robot policy. A visually convincing mesh with the wrong scale can still make the next stage physically infeasible.
The robot learns an expert before it learns the video
The reference workflow starts with an egocentric iPhone demonstration. Reconstructed motion is retargeted to a robot, an expert policy is trained in simulation, and its rollouts supply demonstrations for GR00T N1.7. The documented embodiments are floating Sharpa and Vega Sharpa.
That intermediate expert provides something the camera never recorded: actions in the target robot’s own control space. The video establishes the intended interaction; simulation turns it into experience the action model can consume. Keeping the intermediate artifacts also makes it possible to separate a bad reconstruction from a bad retargeting or a failed learner.
The associated CHORD framework adds contact-wrench guidance. It represents how contact can exert force and torque on an object, rather than merely matching where a human touched it. Nearby contact points can have different mechanical effects, so copying location alone can reward the wrong behavior.
A little real adaptation worked after simulation
For the Vega/Dexmate Sharpa tissue-box task, NVIDIA reports GR00T N1.7 pretraining on 200 successful simulated expert rollouts, followed by five epochs on ten real-robot replays. Those replays came from one expert-generated trajectory; they were not human teleoperation demonstrations. The resulting policy completed four of five real trials.
Starting from raw GR00T N1.7 and adapting on either ten or thirty real replays produced zero successes in five trials. The measured task required lifting the box and placing it stably back on its support. This is a narrow validation: one task, limited real experience and five trials per condition. It does not establish general transfer across objects or environments.
Simply mixing simulated and real episodes was not reliably successful either. The reported Sim100-plus-Real10 and Sim100-plus-Real20 runs each achieved zero of five. Those mixtures also contain fewer simulated examples than the successful staged recipe, so the comparison does not isolate training order. It does show why “more video data” is too loose a description of the intervention.
Three tracks test different breaks in the chain
The challenge separates monocular reconstruction, robotic grounding and end-to-end egocentric transfer. Reconstruction measures geometry and physical plausibility against multi-view references. Grounding fixes G1 with Dex3 hands and tests clean, synthetically corrupted and off-the-shelf reconstructed trajectories. That embodiment belongs to this track, not every toolkit demonstration.
Teams can change their methods between grounding tiers. A high noisy-input score therefore measures a submitted pipeline, not automatically one unchanged policy’s tolerance. The egocentric track permits different overall approaches, including methods that do not explicitly reconstruct every intermediate scene.
Passing a software gate is not completing the task
The tutorial treats each handoff as something to inspect. The E2E guide explicitly separates source-rollout eligibility, dataset/model checks and closed-loop success. An open-loop prediction check can confirm that data reaches the model without proving that its actions work.
That discipline is the wider contribution. Human footage becomes valuable robot experience only after its geometry, embodiment mapping and learning sequence survive separate tests. V2D exposes those dependencies, giving teams a way to improve the conversion process instead of treating a larger video collection as the result.
References
Questions, news tips or corrections? Contact [email protected].