

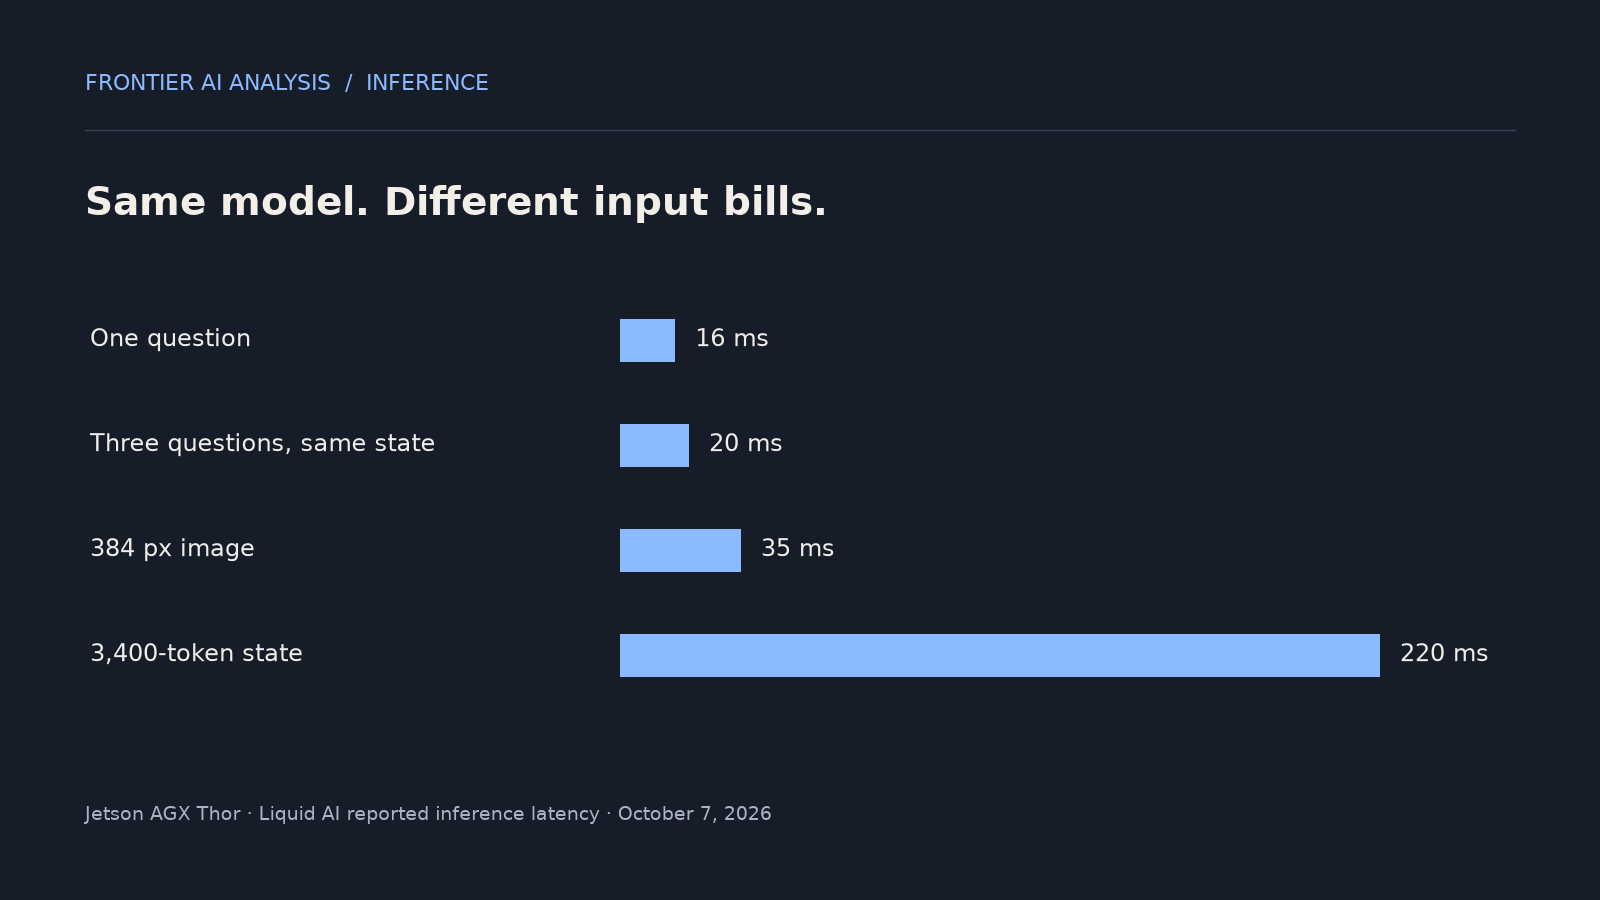
 Inference
Liquid AI’s fast decisions still have to read the world
The revealing number in the d1 release is the small cost of asking three questions about the same scene.
Model-building research and analysis covering NVIDIA.
InferenceThe revealing number in the d1 release is the small cost of asking three questions about the same scene.
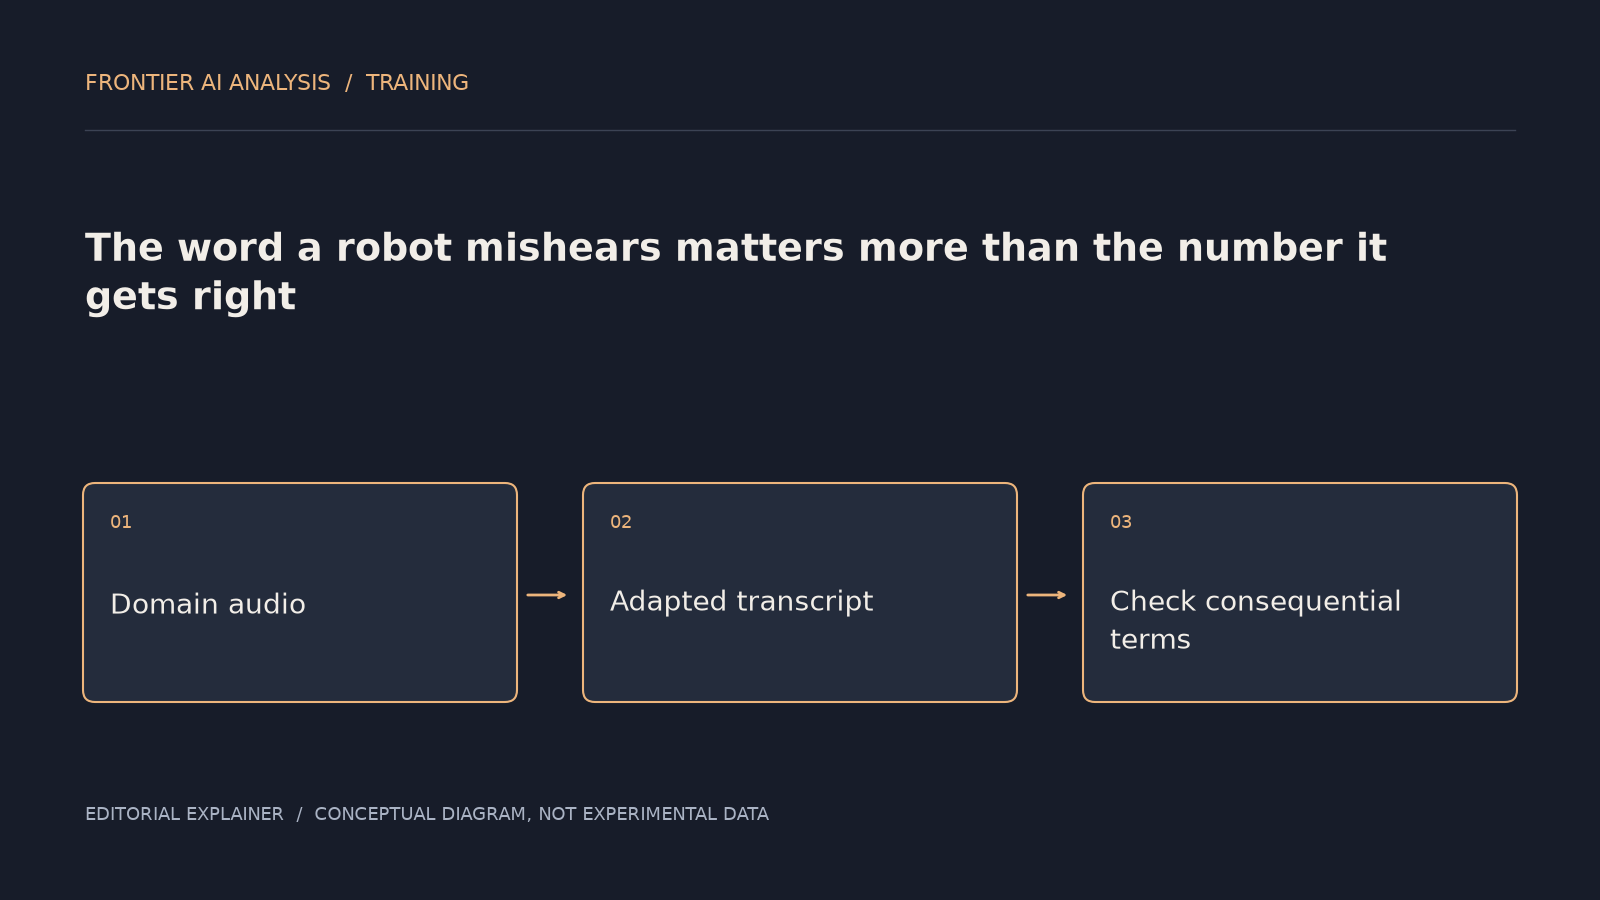 Training
NVIDIA’s aviation speech study shows the value of domain adaptation—and why aggregate transcription scores are only the start for physical interfaces.
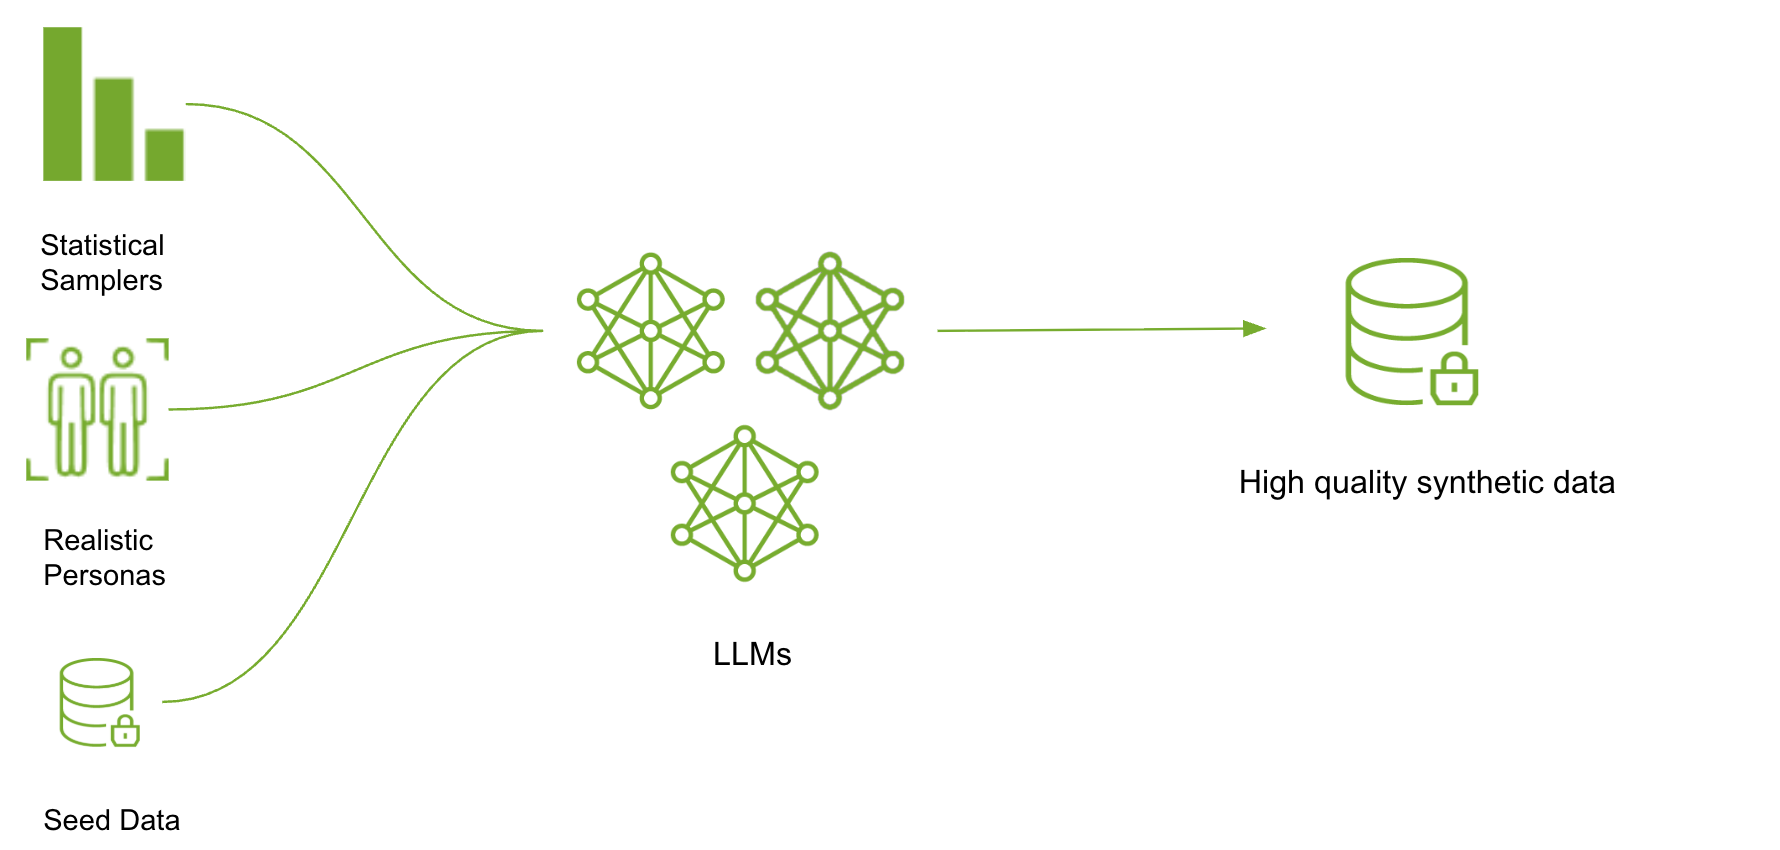 Data
NeMo Data Designer makes fields, dependencies and checks explicit. The useful asset is a reproducible training-data recipe, not the number of generated rows.
 Training
Nemotron 3 Ultra uses four-bit training with higher-precision exceptions. The opportunity is more useful research per budget, provided stability and downstream quality survive.
 Training
Expensive GPUs can still spend time waiting on slower operations. Research from Together AI and five other organizations shows how better scheduling can turn more of that hardware into useful work.
 Inference
Separating long-prompt processing from answer generation can prevent one request from slowing everyone else. The trade is extra transfer time and a more complex service.
 Inference
SGLang, Qwen and NVIDIA compress the memory used by long conversations. The useful saving depends on which answers change and how much repair they need.